Tech Station

学者追踪 › CMU › Guanya Shi

Guanya Shi

Carnegie Mellon University · 最近 45 天 17 篇
#12026-10-28追踪学者 · Guanya Shi

Value Function-Guided MPPI for Hierarchical Planning and Control in Off-Road Autonomous Navigation

Anoushka Alavilli, Raymond Song, Guanya Shi, Jeff Schneider

Autonomous navigation in off-road terrain is commonly achieved using hierarchical control and planning architectures that rely on explicit cost maps and one-way information flow fr…

Autonomous navigation in off-road terrain is commonly achieved using hierarchical control and planning architectures that rely on explicit cost maps and one-way information flow from a high-level planner to a low-level controller, decoupling planning from the true execution cost experienced during control. We propose a hierarchical planning and control framework in which information flows bidirectionally, allowing the low-level controller to guide trajectory selection at the planning level. The highest level of the hierarchy is a Model Predictive Path Integral (MPPI) control-style planner that determines optimal trajectories and passes these waypoints to a pretrained low-level reinforcement learning (RL) controller. Rather than drawing from an explicit cost map, our MPPI planner leverages the value function of the RL controller as an implicit cost representation. In this formulation, MPPI serves as a trajectory exploration mechanism, while the low-level controller's value function guides the search. To account for the distribution shift seen by the value function between training and evaluation, we propose an online policy evaluation process that adapts the value function to unseen driving experiences, and we demonstrate this adaptation in unseen off-road simulation environments. We evaluate our approach in a high-fidelity off-road driving simulator across a range of challenging terrain conditions and compare its performance against a baseline MPPI controller. The results demonstrate that our method achieves safer and more effective navigation to goal locations while eliminating the need for explicit cost maps and enabling tighter coupling between planning and control.

#22026-10-27追踪学者 · Guanya Shi

CARD: Contact-Anchored Retargeting for Dexterous Manipulation

Cunxi Dai, Botao He, Francois R Hogan, Wei Pan, Rao Fu, Wen-Han Hsieh, Ruoshi Liu, Jitendra Malik 等

Humans are dexterous, but traditional data collection paradigms such as teleoperation, kinesthetic teaching, and wearable exoskeletons force humans to act through the robot embodim…

Humans are dexterous, but traditional data collection paradigms such as teleoperation, kinesthetic teaching, and wearable exoskeletons force humans to act through the robot embodiment, bottlenecking their dexterity. Retargeting can avoid this. However, existing methods purely translate kinematics and ignore the real-world contact dynamics essential for task success. We present CARD: Contact-Anchored Retargeting for Dexterous Manipulation, a simulator and object-free framework that retargets human demonstrations to robot actions by explicitly preserving contact force targets. CARD unifies human data sources including video, motion capture, and tactile gloves via a shared hand--contact representation and generates explicit contact force targets in addition to kinematics. To maintain these contact targets during hardware open-loop replay, CARD also introduces a tactile tracking controller. For video which does not contain an explicit tactile source, we present Vid-HACO, our video-to-contact model that sets a new state of the art. Across our video, glove, motion-capture data and the GRAB dataset, CARD maintains contact on $43$--$78%$ of contact frames, while kinematic and object-aware retargeting methods maintain contact on $<10%$ and $22.5%$ of the frames respectively. Further, integrating our formulation into physics-based retargeting improves strict task success from 12% to 32% on GRAB dataset. Finally, we show that our tactile tracker is critical to reproduce demonstrated forces during hardware replay. These results establish that contact preservation via CARD is a scalable interface for transferring human dexterity to robots.

#32026-10-26追踪学者 · Guanya Shi

Learning Force-Reactive Humanoid Loco-Manipulation

Sihang Li, Xiaofeng Guo, Jinkun Cao, Charlie Cheng, Ruihan Yang, Chen Feng, Guanya Shi, Haozhi Qi

Many everyday tasks require controlling contact force as well as motion. On a humanoid, this force must often be coordinated across both hands and the whole body, and cannot be spe…

Many everyday tasks require controlling contact force as well as motion. On a humanoid, this force must often be coordinated across both hands and the whole body, and cannot be specified by kinematic trajectories alone. Therefore, we present FLORE, a framework for learning force-reactive humanoid loco-manipulation. We collect robot-free demonstrations using two force-sensing UMI-style handheld grippers for hand motion and contact wrenches, and wearable trackers for body motion. A force-reactive diffusion policy takes vision, proprioception, and measured wrenches as input, then predicts actions and per-hand force commands. A hybrid compliance whole-body controller with force tracking executes these commands while maintaining balance: an integral of the force error measured by real force/torque (F/T) sensors lets each hand track force accurately along the commanded direction and remain compliant along the others. In simulation, the controller tracks per-hand force commands of varied magnitude and direction, with little loss in whole-body motion accuracy. Across three contact-rich tasks on the robot, the force-reactive policy succeeds in 80% of rollouts, compared with 26.7% for a position-only policy trained on the same demonstrations and executed by the same controller. For more details, please visit our website: https://louis-leee.github.io/FLoRe/.

cs.ROcs.AIcs.LGeess.SY
#42026-10-23追踪学者 · Guanya Shi

DexPort: A Hand-Held Skill Interface for Dexterous Hand Data Collection

Amber Xie, Jiawei Fu, Xiaofeng Guo, Carmelo Sferrazza, Guanya Shi, Haozhi Qi

Collecting high-quality demonstrations remains a central bottleneck for learning dexterous manipulation. Teleoperation records executable robot actions, but it requires a complete …

Collecting high-quality demonstrations remains a central bottleneck for learning dexterous manipulation. Teleoperation records executable robot actions, but it requires a complete robot setup and places the burden of coordinating many finger joints on the operator. Human demonstrations are easier to collect, but their motions must be estimated and retargeted to the robot, and they do not directly provide robot actions. In this paper, we introduce DexPort, a portable data-collection interface for high-DoF robot hands. It uses the same hand hardware for collection and deployment, avoiding a hand embodiment gap, and records both commanded joint targets and measured joint states. Our key observation is that a small set of skills can support a wide range of dexterous tasks. During collection, the operator moves the hand-held interface to specify the robot wrist motion and selects or adjusts skills that coordinate the finger motion. This removes the need to control each joint independently while retaining behaviors such as precise grasping and in-hand manipulation. We collect demonstrations across several real-world tasks and in unstructured environments without a robot arm. We then use behavior cloning to train visuomotor policies directly on the recorded wrist motions and hand commands, without skill labels. We evaluate across 4 tasks: pick-and-place with diverse objects, screwing with in-hand tool use, drawer stowage which requires simultaneous grasp and pulling, and a bimanual scanning task. We collect over 2,500 demonstrations with our portable device, in both laboratory and in-the-wild settings. Across our tasks, we see an improvement from 11% to 64% when using recorded robot commands instead of states, and an improvement from 36% to 78% for task success when using in-the-wild data.

cs.ROcs.AIcs.LG
#52026-10-19追踪学者 · Guanya Shi

EmbodyHOI: Embodiment-Aware Generation of Hand-Object Interactions for Humanoid Dexterous Manipulation

Chaitanya Chawla, Kartik Sharma, Ananya Bal, Laszlo A. Jeni, Guanya Shi

Humanoid dexterous manipulation needs reference motions that are both semantically rich and kinematically feasible for the target robot. Text-conditioned hand-object interaction (H…

Humanoid dexterous manipulation needs reference motions that are both semantically rich and kinematically feasible for the target robot. Text-conditioned hand-object interaction (HOI) generators supply diverse, language-specified demonstrations, but they synthesize motion in human (MANO) space. The embodiment gap is therefore deferred to post-hoc retargeting, where trajectories deployed on the robot can fail to maintain contact with objects and also degrade policy learning. Our key idea is that robot reachability should constrain the interaction trajectories while they are being generated. We present EmbodyHOI, which runs a differentiable inverse-kinematics (IK) solver for a specific humanoid embodiment inside the sampling loop of a frozen flow-matching HOI trajectory generator. We feed back gradients from the embodiment-aware IK solver into the HOI sampler and jointly optimize the position of the humanoid with respect to the object. Because guidance acts only at inference, one HOI trajectory generator trained on human hand poses transfers across humanoid embodiments without retraining. On ARCTIC trajectories with two contrasting humanoids (Unitree G1 and H1-2), our proposed guidance-based method cuts the retargeted wrist error from 8.9 cm to 0.6 cm while leaving text-to-HOI generation quality intact, and raises task success from 68% to 79% on 50 random G1 tasks and from 62% to 76% on a four-task H1-2 suite. Critically, cheaper alternatives for bridging the embodiment gap fail to beat EmbodyHOI. Post-hoc wrist refinement and compute-matched best-of-N selection both reach lower IK energy than our guidance yet train worse policies. For simulation results, see our website: https://embodyhoi.github.io/

#62026-10-19追踪学者 · Guanya Shi

SSIO: Self-Supervised Inertial Odometry

Yuheng Qiu, Yutian Chen, Carlton Cort, Weison Huang, Shibo Zhao, Pieter Abbeel, Rocky Duan, Koushil Sreenath 等

Learning inertial odometry for a new platform usually requires ground-truth trajectories. We show that an inertial odometry model can instead be trained from scratch by a myopic te…

Learning inertial odometry for a new platform usually requires ground-truth trajectories. We show that an inertial odometry model can instead be trained from scratch by a myopic teacher that integrates the IMU over each short window independently, a scheme we call integration self-supervision. Interestingly, although supervised only by short-window velocity changes, the student learns to directly predict velocity, and does so more accurately than its integration teacher. Pose graph distillation then refines the model with sequence-consistent targets from a pose graph over many windows. Training on a new platform therefore no longer requires collecting ground-truth trajectories, but only calibrating the IMU and recording data during normal operation. Across six datasets spanning pedestrians, drones, quadrupeds, and a humanoid, the same recipe with no velocity or position labels trains models that come within 0.07~m/s average velocity error of a same-architecture supervised baseline.

#72026-10-19追踪学者 · Guanya Shi

SWAP: Test-Time Steerable Humanoid Whole-Body Collision Avoidance

Zeji Yi, Guanqi He, Xiaofeng Guo, Guannan Qu, Pieter Abbeel, Yan Duan, Karen Liu, Guanya Shi

Humanoid robots operating in human-centric environments must coordinate the entire body to traverse tight, cluttered spaces while maintaining balance. Existing methods often strugg…

Humanoid robots operating in human-centric environments must coordinate the entire body to traverse tight, cluttered spaces while maintaining balance. Existing methods often struggle to jointly consider dynamic stability and collision avoidance from high-dimensional perceptual inputs. Moreover, for humanoids, safe behavior is inherently multimodal: the same obstacle may admit multiple valid traversals, which is difficult to represent with a single deterministic policy. To address these challenges, we propose SWAP (Steerable Whole-body Avoidance Policy), a hierarchical framework that separates collision-aware decision making from stabilization. A high-level, perception-conditioned diffusion policy generates multimodal, collision-aware motion proposals, while a low-level whole-body RL controller tracks these proposals and maintains dynamic balance. To efficiently train the high-level policy, we obtain scalable supervision via hindsight labeling: we roll out the low-level policy under randomized commands, place obstacles only in the space that each executed motion did not sweep, so the motion is collision-free by construction, and re-render the perception the robot would have seen. At deployment, Monte Carlo sampling with simple cost signals steers the diffusion model toward safe, task-aligned behaviors without heavy reward tuning. Experiments in simulation and on a real Unitree G1 humanoid show reliable avoidance with static and dynamic obstacles. Test-time steering further enables customization, improving targeted rewards (e.g., speed, orientation, or posture) by 34% on average while maintaining a high collision avoidance rate. Together, these results support a practical solution to humanoid whole-body collision avoidance with test-time steerability. Project website: https://iscoyizj.github.io/SWAP-steerable-humanoid-oa-website/

#82026-10-17追踪学者 · Guanya Shi

Action-Aligned Latent Planning for Versatile Humanoid Loco-Manipulation

Yutang Lin, Guanya Shi, C. Karen Liu

Learning a single perceptive policy for diverse humanoid loco-manipulation requires unifying high-level task decisions without losing the state-dependent physical responses that ma…

Learning a single perceptive policy for diverse humanoid loco-manipulation requires unifying high-level task decisions without losing the state-dependent physical responses that make each interaction succeed. This makes the representation between high-level planning and whole-body control critical: kinematic or contact targets provide compact abstractions but do not directly encode interaction-specific control responses, while directly predicting low-level actions requires the planner to model high-frequency closed-loop feedback. We propose FIBER, a framework that uses the executable latent space of a frozen behavioral foundation model (BFM) as a shared planning representation for heterogeneous interaction skills. Our latent policy projection (LPP) maps independently acquired task-specific policies into this representation by identifying latent commands whose induced actions match their local control responses, enabling lower-rate planning while retaining the BFM's high-frequency state feedback. After projection, we aggregate closed-loop latent rollouts from all skills and train a single perceptive flow planner entirely offline. We further introduce AH-BFM, an adaptive-horizon BFM trained with multi-gamma forward-backward (FB) learning to support both precise control and temporally extended whole-body behavior. We evaluate FIBER on box pickup, door opening, and object grasping in simulation and on a real Unitree G1 humanoid. Across 128 diverse variations per task in simulation, FIBER achieves 42.0% mean success, more than tripling projected latent replay (11.6%) and substantially outperforming kinematic planning (3.5%). Real-world experiments further demonstrate sim-to-real transfer, skill chaining, and conditional steering through the same unified planner.

#92026-10-16追踪学者 · Guanya Shi

StopWatch: Goal Grounding for Object-goal Navigation

Xinhao Liu, Yunsheng Tian, Yuheng Qiu, Pieter Abbeel, Xi Chen, Guanya Shi, Chen Feng

Pretrained VLMs bring rich world knowledge and semantic priors to object-goal navigation, and fine-tuning a VLM into a navigation policy has become a common recipe. Despite this pr…

Pretrained VLMs bring rich world knowledge and semantic priors to object-goal navigation, and fine-tuning a VLM into a navigation policy has become a common recipe. Despite this progress, success rates remain low, and it is unclear which capability these fine-tuned policies lack. Our diagnosis identifies goal grounding as the dominant failure. These policies explore well, yet often fail to notice that the goal is already in view or to estimate how far away it is. To address this failure, we ground the goal explicitly. Explicit grounding substantially improves success and reaches state-of-the-art results on six benchmarks across three scene collections. We also correct annotation defects in these benchmarks, so that future methods are evaluated more faithfully. Our analysis on the clean benchmarks shows that, with ground-truth grounding, our policy nearly matches the expert that generated its demonstrations, leaving the headroom in perception rather than policy learning. Our work points to goal grounding as a missing piece of object-goal navigation and offers a simple and effective solution to the task.

#102026-10-14追踪学者 · Guanya Shi

When Do Discrete Actions Make Good Continuous Controllers?

Zeji Yi, Soham Dasgupta, Xinyang Zhang, Koushil Sreenath, Guannan Qu, Xi Chen, Max Simchowitz, Guanya Shi

Though modern AI models like LLMs predict discrete tokens, today's robotic foundation models represent actions as continuous vectors. In this paper, we challenge this common consen…

Though modern AI models like LLMs predict discrete tokens, today's robotic foundation models represent actions as continuous vectors. In this paper, we challenge this common consensus by asking if continuous action parametrizations are superior to their discrete counterparts. We conduct an extensive comparison of single-step regression and multi-step flow variants of both continuous and discrete policies in both from-scratch single-task and multi-task VLA training, in both simulation and on real hardware. In all regimes, we find that discrete action prediction, even the most naive, uniform-bin quantization, can match or even outperform continuous-action policies in task success rate. Moreover, we find that the challenge to discrete action policies is not action precision, but rather factorization error introduced by product-distribution predictions across time and action dimensions. We show that, when paired with the correct interventions (iterative computation through discrete flows, or distribution sharpening through classifier-free guidance), discrete flow policies can turn this weakness into a strength, enabling more responsive action changes during a predicted action chunk. Lastly, we show that attempts to explicitly inject geometric information into discrete policies, e.g. through corruption processes that emulate continuous flow matching, do not yield consistent improvements. Taken together, our findings question existing assumptions that robotic action prediction requires distinct design decisions compared to other AI domains, and motivate the possibility of discrete action prediction as a compelling alternative to today's continuous action parametrizations. Project page: https://iscoyizj.github.io/discrete-action-website/

#112026-10-09追踪学者 · Guanya Shi

Memory Without Curation: Learning Multi-Stream Latent Memory for Robot Policies

Yilin Wu, Rutav Shah, Shuaiyi Huang, Sumedh A. Sontakke, Homanga Bharadhwaj, Andrea Bajcsy, Max Simchowitz, Guanya Shi

It is widely appreciated that robotic policies require long-term memory to perform complex tasks. However, directly conditioning policies on all past observations leaves policy lea…

It is widely appreciated that robotic policies require long-term memory to perform complex tasks. However, directly conditioning policies on all past observations leaves policy learning susceptible to learning spurious shortcuts, and introduces large latency at policy deployment. As such, today's memory-augmented policies curate what to remember, either by retaining only recent frames, selected keyframes, or textual summaries, or by learning latent representations of the visual stream alone. In this work, we propose an alternative approach IMPRINT, a policy-agnostic latent memory framework that augments vision-language-action (VLA) models with multi-stream memory without explicitly constraining what the policy should remember. IMPRINT compresses different streams into a latent memory that is updated incrementally at inference, enabling low latency. To avoid shortcut learning, IMPRINT adopts a two-stage training procedure, first supervising memory to reconstruct multiple streams (observations, actions, proprioception) of past information, as well as estimate current task progress, followed by end-to-end finetuning, jointly with the policy, on action prediction. Across both simulation and real-world tasks demanding memory, IMPRINT improves average success over the base VLA by at least 26%, outperforming popular alternatives, and maintaining lowest inference latency among memory-augmented VLAs. Through careful ablations, we demonstrate the utility of incorporating diverse information streams into robotic memory, validating the advantages of foregoing history curation. Project website: https://yilin-wu98.github.io/imprint_website/.

cs.ROcs.AIcs.LG
#122026-10-08追踪学者 · Guanya Shi

PanTact: Teaching Whole-Body Dexterity with a Wearable Contact Interface

Xiaomeng Xu, Han Zhang, Zhian Ruan, Xiaofeng Guo, Jinkun Cao, Ruihan Yang, Carmelo Sferrazza, Shuran Song 等

Humanoid robots have many degrees of freedom and contact surfaces, yet most loco-manipulation research restricts manipulation to the hands and avoids other body contacts with the e…

Humanoid robots have many degrees of freedom and contact surfaces, yet most loco-manipulation research restricts manipulation to the hands and avoids other body contacts with the environment. To extend manipulation beyond the hands, we present PanTact, a system that learns humanoid whole-body dexterity, the capability to manipulate with any suitable body surface, directly from robot-free human demonstrations. Our key idea is to use contact as manipulation-centric information that transfers across embodiments. Contact locations and timing specify the interactions needed to accomplish a task, while the robot chooses how to coordinate its body to realize them within its own physical constraints. Specifically, PanTact captures, learns, and executes whole-body contact via: 1) a wearable, robot-free data collection interface that augments egocentric vision and bimanual UMI grippers with whole-body modular contact patches to record body contact locations and states; 2) a visuomotor policy that mitigates the egocentric observation gap and predicts whole-body contact goals; and 3) contact-aware whole-body control formulations that realize active contact goals using suitable robot surfaces. We deploy PanTact on a Unitree G1 humanoid without additional body contact sensors, demonstrating whole-body dexterity involving body support, pushing, sweeping, and load-sharing. Website: https://pantact.github.io

#132026-10-08追踪学者 · Guanya Shi

Fly-by-Code: Embodied Coding Agents for Aerial Manipulation with Active Visual and Physical Feedback

Jaewoo Lee, Jeongyeon Seo, Sihyun Cho, Gyeongrak Choe, Yutong Wang, Bavin Saravanan, Jia-Bin Huang, Furong Huang 等

Embodied coding agents construct robot policies from natural-language instructions by generating executable programs and refining them from execution feedback. This refinement assu…

Embodied coding agents construct robot policies from natural-language instructions by generating executable programs and refining them from execution feedback. This refinement assumes that execution feedback reveals whether the task succeeded and, after a failure, provides sufficient evidence to guide program revision. Aerial manipulation violates this assumption in two ways. Payload constraints restrict onboard camera coverage and leave task-critical outcomes outside the robot's view (partial observability), while strong dynamic coupling and limited control margins make physical interactions fragile (limited interaction robustness) and leave failure causes unresolved. Re-examining the same feedback cannot recover observations that were never collected or separate failure causes that the available evidence does not distinguish. To acquire this missing evidence, we introduce Active Feedback (AF), an active "View and Probe" framework. When execution feedback leaves unresolved questions, the agent synthesizes a separate diagnostic program that runs in simulation to inspect unseen outcomes from informative viewpoints (View) or test hypotheses about failure causes through targeted physical interactions (Probe). Across six simulated aerial manipulation tasks with 60 trials per condition, AF reduces false completion declarations from 25 to 5 and raises final task success from 31.7% to 75% compared with terminal feedback under the same coding-agent configuration and task-execution limit. Using shared robot APIs, task programs refined with AF in simulation run on a physical aerial manipulator without task-program source-code modification and complete multi-stage manipulation tasks in the real world. These results show that executable diagnosis fills gaps in execution feedback for embodied coding agents, improving both completion assessment and program refinement in aerial manipulation.

cs.ROcs.CVcs.LG
#142026-10-07追踪学者 · Guanya Shi

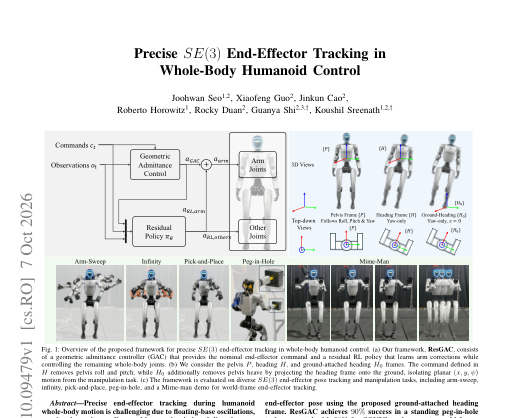
Precise SE(3) End-Effector Tracking in Whole-Body Humanoid Control

Joohwan Seo, Xiaofeng Guo, Jinkun Cao, Roberto Horowitz, Rocky Duan, Guanya Shi, Koushil Sreenath

Precise end-effector tracking during humanoid whole-body motion is challenging due to floating-base oscillations, gravity, dynamic coupling, and locomotion-induced disturbances. We…

Precise end-effector tracking during humanoid whole-body motion is challenging due to floating-base oscillations, gravity, dynamic coupling, and locomotion-induced disturbances. We propose ResGAC, a whole-body humanoid controller for precise end-effector pose tracking that combines geometric admittance control (GAC) with residual reinforcement learning. GAC provides structured $\SE$ task-space feedback and generates nominal arm joint-position targets, while residual RL compensates for unmodeled dynamics and coordinates locomotion and balance in the shared joint-position action space. The left-invariant geometric formulation allows the same GAC law to be used across manipulation reference frames. This enables the use of a ground-attached heading frame that preserves planar locomotion while removing pelvis roll, pitch, and heave from the manipulation reference, thereby reducing reference-induced end-effector motion during locomotion. ResGAC is validated on a real Unitree G1 humanoid. Across four standing end-effector tracking benchmarks, ResGAC consistently outperforms representative baselines, including SONIC, achieving lower translational and rotational errors. Real-world experiments further demonstrate reduced propagation of pelvis motion to the desired end-effector pose using the proposed ground-attached heading frame. ResGAC achieves $90%$ success in a standing peg-in-hole task compared with $50%$ for SONIC, and accurate world-frame $\SE$ end-effector pose tracking during lower-body motion. Experimental videos are included in the supplementary material and are also available on the project website: https://resgac.github.io/ResGAC-website/.

#152026-10-05追踪学者 · Guanya Shi

Trajectory Planning without Trajectory Data: A Manifold-Guided Approach

Silong Yong, Anji Liu, Cunxi Dai, Carl Busart, Guanya Shi, Yilun Du, Katia Sycara, Yaqi Xie

A common way for trajectory planning is to leverage generative models trained on large collections of expert trajectories. At inference time, the model generates executable traject…

A common way for trajectory planning is to leverage generative models trained on large collections of expert trajectories. At inference time, the model generates executable trajectories by conditioning on task goal constraints. However, trajectory-based methods rely on costly supervision, scale poorly with sequence length, and often generalize poorly to unseen constraints such as novel start-goal pairs. We propose an alternative to learn the underlying state-space manifold and use the geometry of the manifold for trajectory planning. This approach requires only state observations and enables generalization to unseen constraints by con- structing trajectories on the learned manifold of the state space. Experiments on Maze2D and robotic motion-planning benchmarks show that Ariadne constructs feasible paths from state-only supervision and generalizes to unseen start-goal combinations. On high-dimensional dual-arm planning, it remains competitive with trajectory-supervised and classical planners, while requiring no trajectory data for training.

#162026-09-30追踪学者 · Guanya Shi

SimEX: Simulation-Integrated Robotics AutoResearch

Jiaheng Hu, Roberto Martin-Martin, Peter Stone, Rocky Duan, Zhenyu Jiang, Guanya Shi

Coding agents powered by large language models (LLMs) have shown remarkable abilities to autonomously reason about and achieve goals in the digital world. However, bringing this su…

Coding agents powered by large language models (LLMs) have shown remarkable abilities to autonomously reason about and achieve goals in the digital world. However, bringing this success to the physical world remains challenging. On the one hand, direct generation methods (e.g., Code as Policies) often suffer from the LLMs' insufficient understanding of robots and physical environments. On the other hand, iterative trial-and-error tuning in the physical world (e.g., physical autoresearch) induces significant experimental cost and safety concerns. We introduce SimEX: Simulation-Integrated Robotics AutoResearch, an autoresearch framework that tightly integrates simulated experimentation, enabling coding agents to efficiently acquire physical capabilities for controlling real robots. SimEX operates in two stages. First, the agent conducts open-ended probe-and-optimize iterations in simulation, developing a robot toolbox with robust and generalizable capabilities. Second, the agent adapts the toolbox and the simulator together through only a few physical trials: each trial corrects the simulator, and the corrected simulator is used to diagnose failures and screen candidate repairs. We evaluate SimEX extensively in sim-to-sim settings and on physical robots. On challenging real-world manipulation tasks including towel folding, barcode scanning, and plate manipulation, SimEX enables coding agents to efficiently acquire robot skills without any demonstration and with only 10 minutes of real-robot interaction. These results suggest that simulation can be a critical component in achieving physical intelligence, not only as a source of training data that must closely replicate the real world, but also as a roughly correct laboratory where a coding agent develops the knowledge and procedures needed to act on the robot. More details and robot videos at https://robo-simex.github.io/

cs.ROcs.AIcs.LG
#172026-09-29追踪学者 · Guanya Shi

Counterfactual Video Generation Enables Scalable Humanoid Loco-Manipulation

Zihan Wang, Zhen Wu, Pieter Abbeel, Rocky Duan, Jitendra Malik, Carmelo Sferrazza, C. Karen Liu, Guanya Shi 等

Teaching humanoids loco-manipulation skills, such as carrying diverse objects, via visual imitation is a promising path toward generalist robots. However, collecting diverse, high-…

Teaching humanoids loco-manipulation skills, such as carrying diverse objects, via visual imitation is a promising path toward generalist robots. However, collecting diverse, high-quality interaction videos, such as clips that clearly show a person's full body and unoccluded interactions with objects, poses a practical barrier to scaling this approach. We propose PRISM, a real-to-sim-to-real framework that overcomes this limitation by amplifying a handful of real videos into a large, diverse training set. PRISM first generates hundreds of diverse "counterfactual" human-object interaction videos via video-to-video (V2V) generation from a few exemplar real videos. Our contact-anchored real-to-sim pipeline then reconstructs both human and object motions, retargeting this imperfect video data into physically plausible trajectories. The intra-class variability across these counterfactual videos lets us train a single policy that generalizes to unseen objects within each category. We demonstrate the full pipeline by deploying this policy on a real robot without any real-world fine-tuning. Using only onboard depth observations, our humanoid picks up, carries, and drops objects, including boxes, barrels, bins, and balls, across novel instances, sizes, and initial configurations.

cs.ROcs.CVcs.GR

同实验室的其他学者